I tested Clever AI Detector using real benchmark data, but the results were mixed. I’m looking for help interpreting its AI detection accuracy and deciding whether it’s reliable compared with other AI content detectors.
A 0.7% detection rate is the number that stopped me. That result came from humanized AI text, not some unusual edge case buried in a lab setup. The same detector did reasonably well on untouched output, then became almost blind once the writing had been reworked. That gap seems far more useful than the familiar near-perfect accuracy claims.
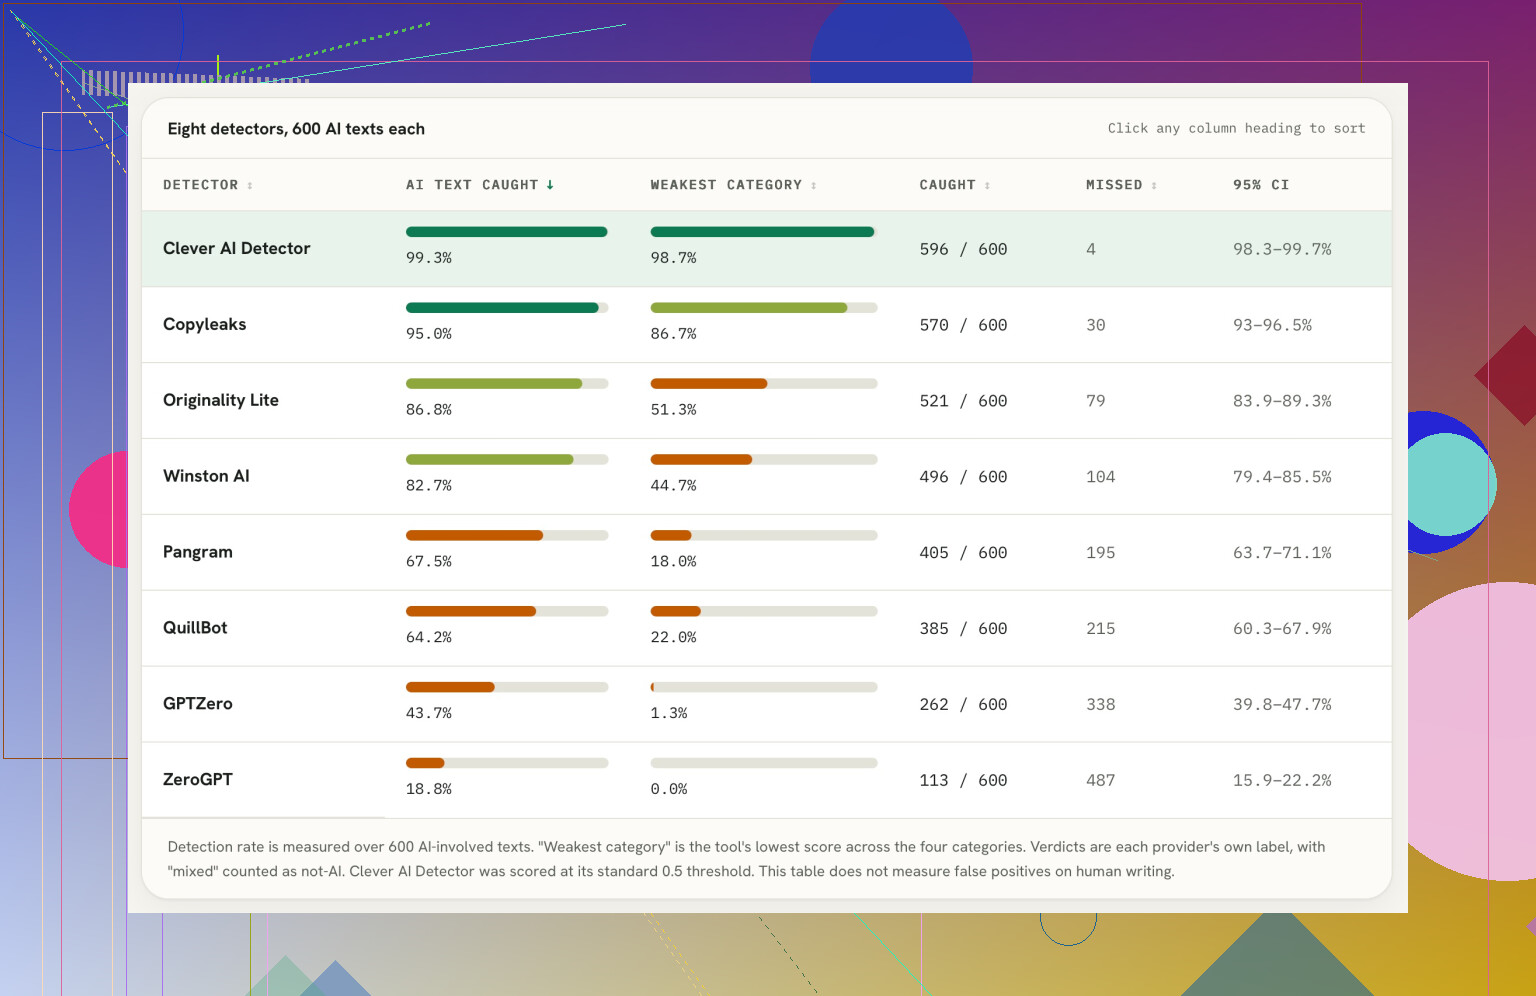
The comparison that matters
The underlying material comes from GEDE, or Generative Essay Detection in Education, created by Lukas Gehring and Benjamin Paaßen at Bielefeld University. It is a public research dataset containing human essays alongside a much larger collection of writing generated or modified by language models. More importantly, it covers varying degrees of AI involvement rather than treating every machine-assisted essay as the same thing. The primary materials are available in the GEDE research paper and the GEDE dataset code.
A later online benchmark selected 600 texts from GEDE, divided them evenly among direct, rewritten, improved, and humanized AI categories, then ran them through the tools listed below. I could not independently establish who conducted that comparison or whether an outside organization supervised it. That caveat matters. Still, the public dataset at least makes the test method potentially reproducible, which is more than can be said for plenty of glossy accuracy badges.
| Detector | Direct AI | Humanized AI |
|---|---|---|
| Clever AI Detector | 100% | 98.7% |
| Copyleaks | 100% | 93.3% |
| Originality.ai Lite | 100% | 51.3% |
| Winston AI | 100% | 44.7% |
| Pangram | 100% | 64.0% |
| QuillBot | 100% | 22.0% |
| GPTZero | 92.7% | 73.3% |
| ZeroGPT | 70.0% | 0.7% |
Editing separates the field
My read is that direct AI detection is barely a differentiator. Nearly every tool catches untouched output, so scoring well there is like bragging that a calculator handled addition. Once the text is humanized, the spread becomes much harder to ignore. Some detectors lose roughly half their effectiveness, while others fall much further. The ordering also shifts, which suggests these systems are not all responding to the same signals.
The omitted AI-improved results point in the same direction. Clever led that category, Originality.ai Lite followed closely, and Copyleaks remained competitive. GPTZero, by contrast, was near the bottom. Across the complete benchmark, Clever ranked first overall and Copyleaks was the nearest alternative. The tested product can be found as Clever AI Detector.
I also ran some text through it myself. The interface is straightforward: paste the writing, start the check, and receive an AI score with highlighted passages that influenced the result. There is not much ceremony, which I appreciate because detector dashboards do not need to resemble aircraft cockpits. It is currently free and allows up to 10,000 words per check through the free Clever AI Detector.
5 Likes
Those numbers only measure missed AI text, not false accusations against human writing. Until Clever is tested on a large human-written control set, 99.3% recall alone doesn’t prove it’s reliable enough for grading or enforcement.
A leaderboard built from one public corpus can flatter the detector that is best tuned to that corpus.
That does not mean the Clever AI Detector numbers are wrong. It means independence matters. If a vendor has seen GEDE, tested against it during development, or adjusted thresholds after checking similar samples, the final score is closer to optimization than a blind evaluation. This can happen without anyone deliberately gaming the benchmark. Repeatedly testing on the same public dataset gradually turns it into part of the development process.
The percentages look more dramatic than the raw counts, too. In each 150-text category, 98.7% means 148 detections and two misses. Clever apparently caught 596 of the 600 AI-derived samples. That is a strong result, but 600 essays from one source still tell us less than several independent sets covering different models, subjects, writing lengths, languages, and editing methods.
There is another comparison problem: what counted as “caught”? These tools return different scores and labels. A detector using an aggressive threshold may catch nearly every AI sample while flagging more ordinary writing. A conservative detector may look worse in this table while causing fewer false accusations. Unless the benchmark locked comparable decision rules before testing, the ranking is not necessarily apples to apples.
I would want a follow-up run where the evaluators:
- choose unseen texts from a separate dataset
- record the detector versions and settings
- lock the scoring threshold in advance
- test human essays matched by topic, length, and skill level
- publish the actual per-document outputs, not only percentages
- include lightly AI-assisted human writing, since that is common and hard to classify cleanly
The last category is especially important. A student might write an essay and use an AI tool to fix grammar in a few paragraphs. Calling the entire document “AI-written” may be technically convenient for a benchmark, but it is not a very useful verdict in a real classroom.
So I would treat Clever’s showing as promising evidence that it handles transformed AI text better than several competitors under this particular setup. I would not call it proven to be 99.3% accurate in general, and I definitely would not let that score decide grading, discipline, hiring, or publication by itself. For low-stakes screening, it may be useful. For enforcement, the detector should provide a lead for human review, not a verdict.
Catching 596 AI samples in a set where every sample is known to involve AI is very different from scanning 600 ordinary student submissions where most are probably human. The second case is where the numbers can become misleading because the real-world base rate matters.
Take a hypothetical class pool of 1,000 essays where 10% contain substantial AI writing. Even if Clever catches 99 of those 100, a 5% false-positive rate on the other 900 would flag another 45 human essays. That means nearly a third of all flagged papers would be false alarms. Clever’s actual false-positive rate might be lower or higher, but this benchmark gives us no way to calculate it.
That is why I would not compare these detectors purely by “overall caught.” For practical use, I would want to know how precise the flags are at the default threshold. Highlighted passages are useful for locating text that deserves a closer look, but they do not show authorship or prove misconduct. Formulaic introductions, heavily edited prose, non-native English, and rigid academic templates can all create text patterns that detectors may treat oddly.
So Clever AI Detector appears very good at recognizing the four AI-derived categories in this particular test. That makes it a reasonable screening option and gives it an advantage worth investigating. It still cannot be called reliable in the broader sense until someone tests it blindly on a realistic mixture of human, AI, and genuinely mixed-authorship writing. For now, I would read its score as “review this passage,” not “this person definitely used AI.”
I’d expect any detector to be less certain about a 200-word excerpt than a full essay, and that is what confused me about this benchmark.
It does not say whether each tool received complete essays, identical excerpts, or text trimmed to fit input limits. That could affect the scores a lot. Clever AI Detector may perform extremely well on full-length academic writing but give less stable results when someone checks only a suspicious paragraph.
The earlier points about false positives still matter, but input length seems like another basic detail needed to reproduce the ranking. I would treat the result as promising for this exact testing format, not proof that every 98% score shown to a normal user has the same meaning.
A realistic expectation is that the same document should receive roughly the same verdict after harmless formatting changes. I would want to see what happens when citations, headings, quoted material, bullet points, or a reference list are added or removed. If those changes swing the score substantially, then a 99.3% detection rate on clean benchmark text may not translate well to ordinary submissions.
That kind of stability matters because users rarely paste perfectly standardized essays. Some upload the whole paper, while others exclude quotations or check only selected paragraphs. Clever AI Detector’s result looks encouraging, especially on modified AI text, but the benchmark does not show whether its score is consistent across those different input choices.
My cautious take is that Clever is worth using as an initial check, not as an authorship decision. If it flags a document, I would inspect the highlighted passages and compare them with drafts, sources, and revision history. A useful follow-up benchmark should test the same essays under minor formatting and editing variations, then report how often each detector changes its verdict.
A tool built by a company that also sells an AI humanizer flagging humanized text at 98.7% is the part that makes me raise an eyebrow. Not saying the numbers are cooked, but a vendor whose main product rewrites AI to dodge detectors has every reason to know exactly what those dodges look like. That cuts both ways, so read the score with that context.
@shadowwolf2011sync and @0xcoder9 already nailed the real gap, which is the missing human control set, so I won’t repeat it. The thing nobody mentioned: even a low false positive rate hits the same students over and over. Non-native writers and anyone with a plain, formulaic style get flagged repeatedly, not randomly. A 5% rate isn’t spread evenly across a class, it lands on the same handful of people every assignment.
So my honest take is it’s fine as a ‘look closer here’ nudge and probably genuinely good at spotting transformed AI, but I wouldn’t hang any decision on it. Screening yes, verdict no.